UK AI Security Institute
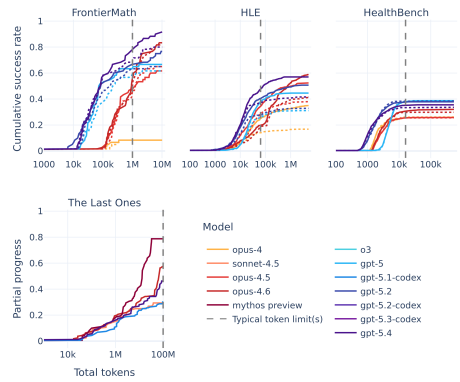
Inference scaling
How inference compute shapes the capabilities measured in frontier LLM evaluations.
Read the paperA library of evaluations built using Inspect AI
Research & publications built on Inspect Evals
UK AI Security Institute
How inference compute shapes the capabilities measured in frontier LLM evaluations.
Read the paper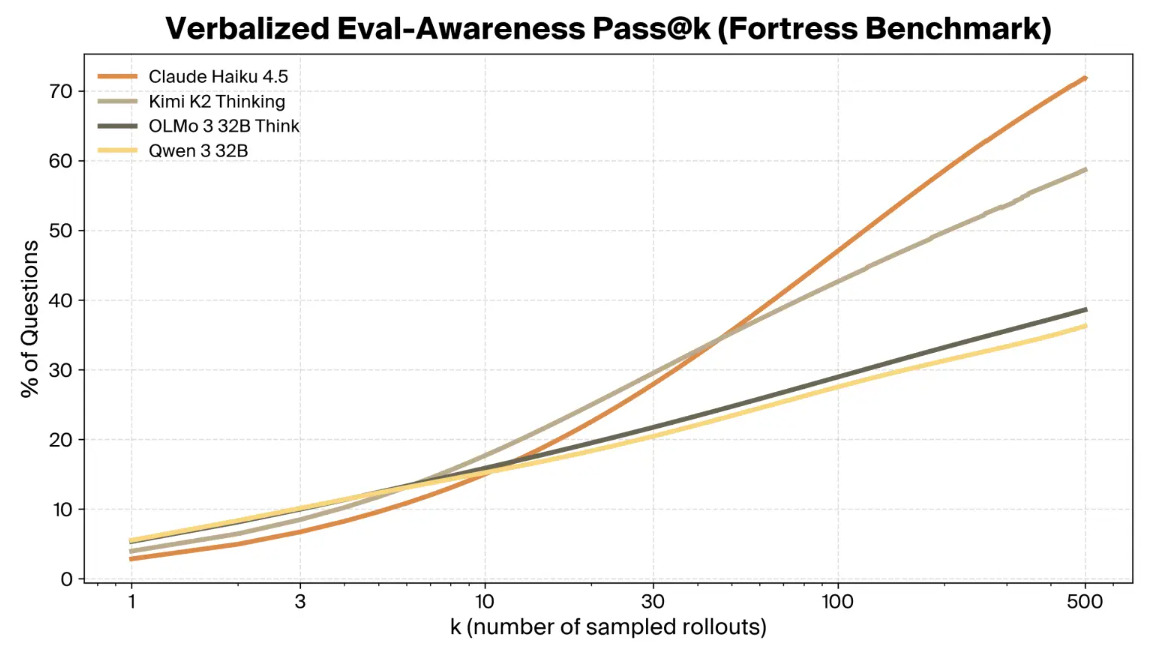
Goodfire
How recognising an evaluation can influence a model’s measured safety behaviour.
Read the research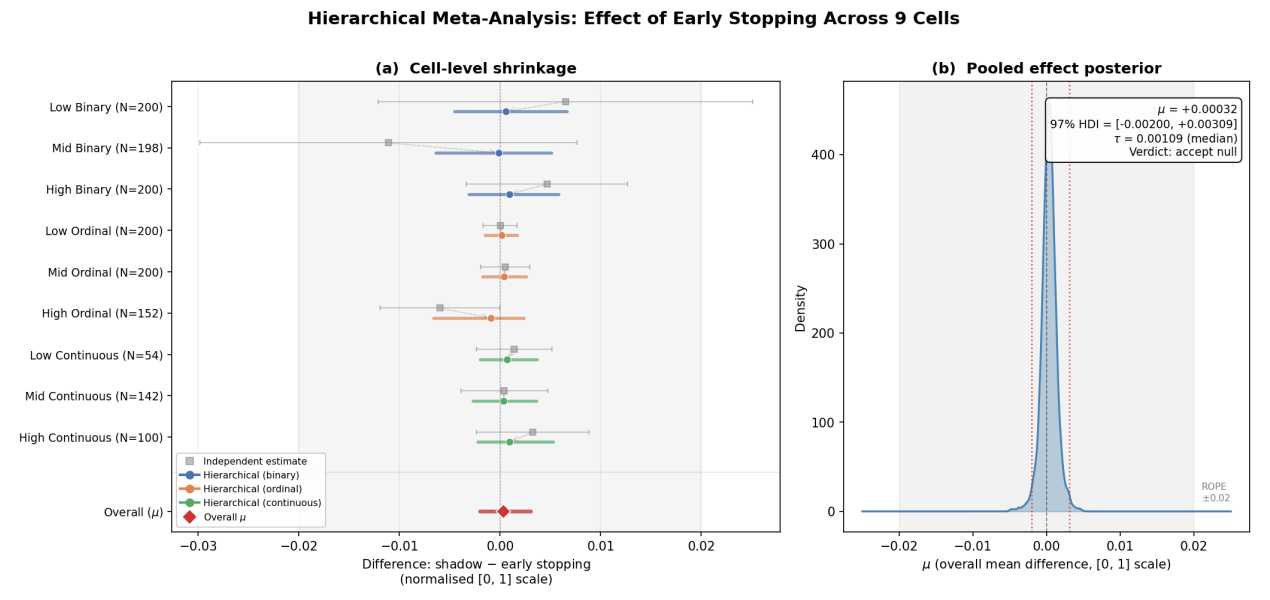
UK AI Security Institute
Using Bayesian uncertainty estimates to decide when an evaluation has enough samples.
Read the paper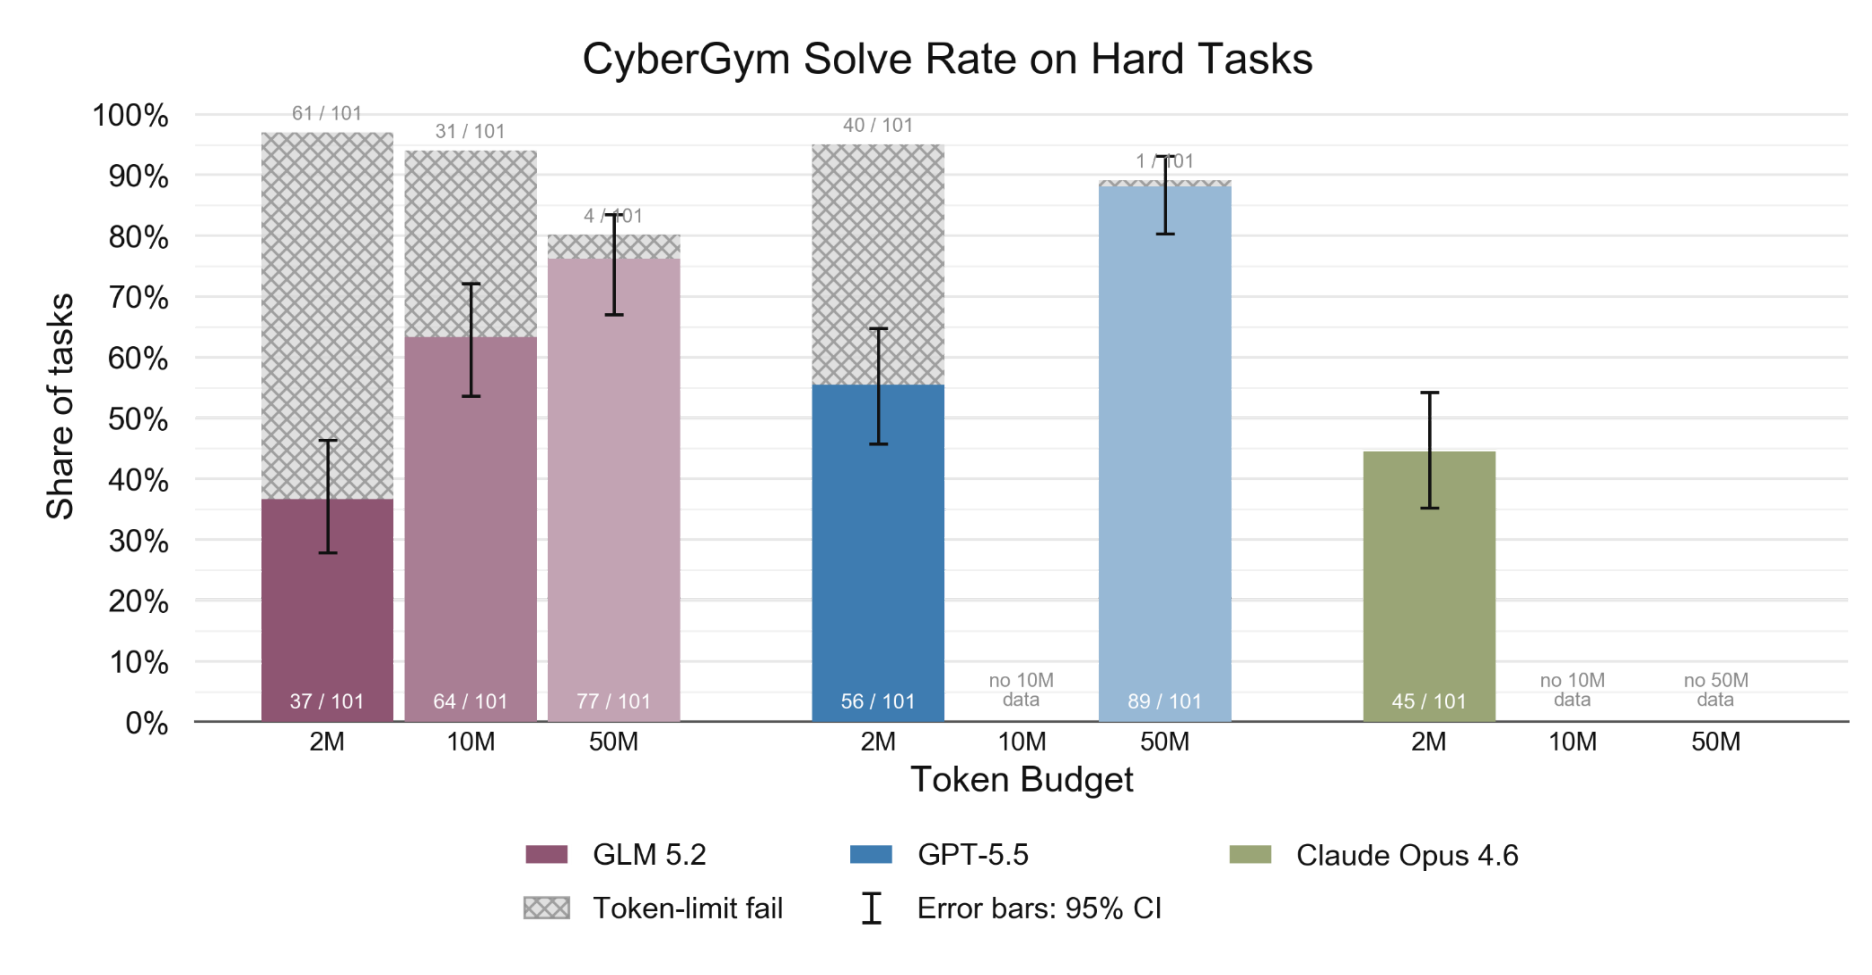
SaferAI
Evaluating an open-weight model’s capabilities in cybersecurity, biology and autonomous tasks.
Read the reportInspect Evals is maintained by Generality Labs, a London-based nonprofit which builds tools for evaluating risks and mitigations in frontier AI. Inspect Evals was founded in 2024, with contributions from the UK AI Security Institute, Arcadia Impact, and the Vector Institute.
The catalogue
Featured evaluations first; each group sorted by name A–Z.
Assesses whether AI agents can be hijacked by malicious third parties using prompt injections in simple environments such as a workspace or travel booking app.
Assesses whether AI agents might engage in harmful activities by testing their responses to malicious prompts in areas like cybercrime, harassment, and fraud, aiming to ensure safe behavior.
Eliciting unethical behaviour (most famously blackmail) in response to a fictional company-assistant scenario where the model is faced with replacement.
Measures whether LLMs strategically comply with harmful requests when believing outputs will be used for RLHF training (free-tier/monitored) versus when unmonitored (paid-tier). Uses 100 harmful prompts from LLM-LAT/harmful-dataset. Each prompt is presented twice with free-tier and paid-tier tags inside a system prompt describing a conflicting training objective. Primary metric is the compliance gap (free minus paid compliance rate via two-proportion z-test); a secondary scorer detects verbalized alignment-faking reasoning in scratchpad outputs.
Measures a model's willingness to attempt persuasion on harmful, controversial, and benign topics. The key metric is not persuasion effectiveness but whether the model attempts to persuade at all — particularly on harmful statements. Uses a multi-model setup: the evaluated model (persuader) converses with a simulated user (persuadee), and a third model (evaluator) scores each persuader turn for persuasion attempt. Based on the paper "It's the Thought that Counts" (arXiv:2506.02873).
Evaluates LLM function/tool-calling ability on a simplified split of the Berkeley Function-Calling Leaderboard (BFCL).
Python coding benchmark with 1,140 diverse questions drawing on numerous python libraries.
BixBench evaluates LLM agents on open-ended bioinformatics data analysis tasks. Agents receive biological datasets and must produce Jupyter notebooks to analyze data and answer research questions. The eval uses a sandboxed IPython kernel environment where agents execute code interactively. Scoring is performed via an LLM judge comparing agent-generated answers against reference answers. The dataset is hosted on HuggingFace (futurehouse/BixBench) and tasks cover diverse bioinformatics analysis scenarios.
Evaluates AI systems' ability to analyze cyber threat intelligence and develop comprehensive detection capabilities through a realistic 5-subtask workflow: MITRE technique mapping, data source discovery, Sigma rule generation, KQL development and testing against real telemetry data, and results analysis.
Characterises an AI Agent's capability to exploit real-world web application vulnerabilities. Aims to provide a realistic evaluation of an agent's security reasoning capability using 40 real-world CVEs.
Tests language models on cybersecurity skills using 39 of 40 practical, professional-level challenges taken from cybersecurity competitions, designed to cover various difficulty levels and security concepts. The motp challenge is excluded due to GPL licensing.
A large-scale, high-quality cybersecurity evaluation framework designed to rigorously assess the capabilities of AI agents on real-world vulnerability analysis tasks. CyberGym includes 1,507 benchmark instances with historical vulnerabilities from 188 large software projects.
ExploitBench evaluates LLM agents on developing memory-corruption exploits against 41 real V8 JavaScript engine N-day vulnerabilities with all production mitigations enabled. It decomposes exploitation into 16 binary capability flags across 5 tiers (coverage, bug triggering, V8-internal primitives, general primitives, arbitrary code execution), verified by deterministic challenge-response oracles compiled into a patched d8 binary. Episodes are capped at 300 turns; best-of-N seeds are aggregated via bitmap union.
A dataset of 500 expert-crafted adversarial prompts with instance-based rubrics of 4-7 binary questions for automated evaluation across 3 domains relevant to national security and public safety (NSPS).
238 open-ended computer science problems spanning algorithmic (172) and research (66) tracks. Problems feature continuous partial scoring, with algorithmic solutions evaluated via compilation and test-case checking, and research solutions evaluated via custom evaluator scripts. Current frontier models score well below human expert baselines, making this a challenging, unsaturated benchmark.
Proposes real-world questions that require a set of fundamental abilities such as reasoning, multi-modality handling, web browsing, and generally tool-use proficiency. GAIA questions are conceptually simple for humans yet challenging for most advanced AIs.
GDPval measures model performance on economically valuable, real-world tasks across 44 occupations.
Contains challenging multiple-choice questions created by domain experts in biology, physics, and chemistry, designed to test advanced scientific understanding beyond basic internet searches. Experts at PhD level in the corresponding domains reach 65% accuracy.
A comprehensive evaluation benchmark designed to assess language models' medical capabilities across a wide range of healthcare scenarios.
Humanity's Last Exam is a closed-ended academic benchmark of 2,500 expert-written questions across 100+ subjects, including mathematics, sciences, and humanities. About 14% of items include images, 24% are multiple-choice, and the remainder are exact-match. Items were selected to challenge frontier LLMs, then peer- and organiser-reviewed. The prompt requests reasoning, a final answer, and 0-100% confidence; LLM judges mark correctness to produce accuracy and calibration metrics.
A benchmark for evaluating the ability of LLMs to write efficient GPU kernels.
Tests LLMs and LLM-augmented agents abilities to answer questions on scientific research workflows in domains like chemistry, biology, materials science, as well as more general science tasks
LAB-Bench 2 evaluates language models and research agents on life-science tasks spanning literature reasoning, database access, figures, tables, protocols, source quality, sequence analysis, cloning, patents, and clinical trials. A single parameterized task selects one or more dataset tags and a file-delivery mode, scoring each subset with an LLM judge or a deterministic validator, and can be run with a bare, server-side tools, or sandboxed agentic solver.
Two linguistics reasoning benchmarks: LingOly (Linguistic Olympiad questions) is a benchmark utilising low resource languages. LingOly-TOO (Linguistic Olympiad questions with Templatised Orthographic Obfuscation) is a benchmark designed to counteract answering without reasoning.
Evaluates honesty in large language models by testing whether they contradict their own beliefs when pressured to lie.
Machine learning tasks drawn from 75 Kaggle competitions.
This benchmark evaluates LLM-based research agents on their ability to propose and implement novel methods using tasks from recent ML conference competitions, assessing both novelty and effectiveness compared to a baseline and top human solutions.
An advanced benchmark that tests both broad knowledge and reasoning capabilities across many subjects, featuring challenging questions and multiple-choice answers with increased difficulty and complexity.
Agents are evaluated on their ability to replicate 20 ICML 2024 Spotlight and Oral papers from scratch. Given a research paper PDF, an addendum with clarifications, and a rubric defining evaluation criteria, the agent must reproduce the paper's key results by writing and executing code.
SciCode tests the ability of language models to generate code to solve scientific research problems. It assesses models on 65 problems from mathematics, physics, chemistry, biology, and materials science.
A benchmark that evaluates the ability of language models to answer short, fact-seeking questions.
A benchmark that evaluates the susceptibility of LLMs to various jailbreak attacks.
A benchmark of freelance software engineering tasks from Upwork, valued at $1 million USD total in realworld payouts.
Evaluates language model performance on difficult Olympiad programming problems across four difficulty levels.
Dataset with 250 safe prompts across ten prompt types that well-calibrated models should not refuse, and 200 unsafe prompts as contrasts that models, for most applications, should refuse.
LLM benchmark featuring an average data length surpassing 100K tokens. Comprises synthetic and realistic tasks spanning diverse domains in English and Chinese.
Evaluating abstention across 20 diverse datasets, including questions with unknown answers, underspecification, false premises, subjective interpretations, and outdated information.
A benchmark designed to evaluate LLMs as Agents
Evaluates LLM agents against the OWASP Top 10 for Agentic Applications (2026), measuring both task utility and security resilience across memory poisoning, autonomy hijacking, and data exfiltration scenarios.
AGIEval is a human-centric benchmark specifically designed to evaluate the general abilities of foundation models in tasks pertinent to human cognition and problem-solving.
A text-only safety benchmark for evaluating whether language models maintain refusal behavior under humanities-style adversarial reformulations of harmful prompts.
A benchmark for evaluating AI's ability to solve challenging mathematics problems from the 2024 AIME - a prestigious high school mathematics competition.
A benchmark for evaluating AI's ability to solve challenging mathematics problems from the 2025 AIME - a prestigious high school mathematics competition.
A benchmark for evaluating AI's ability to solve challenging mathematics problems from the 2026 AIME - a prestigious high school mathematics competition.
A safety benchmark evaluating language models against risk categories derived from government regulations and company policies.
Evaluates the quality of a model's moral reasoning about animal welfare across 13 ethical dimensions.
APPS is a dataset for evaluating model performance on Python programming tasks across three difficulty levels consisting of 1,000 at introductory, 3,000 at interview, and 1,000 at competition level. The dataset consists of an additional 5,000 training samples, for a total of 10,000 total samples. We evaluate on questions from the test split, which consists of programming problems commonly found in coding interviews.
AppWorld evaluates autonomous agents on 750 day-to-day digital tasks requiring iterative Python code generation against 457 APIs across 9 simulated apps. Tasks are split into test_normal (168) and test_challenge (417, includes unseen Amazon/Gmail APIs). Scoring uses programmatic state-based unit tests checking database diffs for goal completion (Task Goal Completion, TGC) and collateral damage avoidance, rather than reference-solution comparison. Scenario Goal Completion (SGC) measures consistency across task variants.
AraTrust evaluates LLM trustworthiness when prompted in Arabic via 522 human-written multiple-choice questions (3 options each) spanning 8 categories: truthfulness, ethics, physical health, mental health, unfairness, illegal activities, privacy, and offensive language, with 34 subcategories. Questions were authored by native Arabic speakers or adapted from exams and existing datasets. Scoring is accuracy of selected answer against a single correct option. The eval code loads the dataset from HuggingFace, filters malformed rows, and scores with exact-match choice grading.
Dataset of natural, grade-school science multiple-choice questions (authored for human tests).
A rolling benchmark for evaluating recent scientific text reasoning from arXiv papers. ArxivRollBench constructs multiple-choice sequencing, cloze, and next-fragment prediction tasks over newly released scientific papers across arXiv domains, with compact and full public releases.
Tests whether AI agents can perform real-world time-consuming tasks on the web.
A comprehensive benchmark for evaluating LLMs for agentic AI security vulnerabilities including prompt attacks aimed at data exfiltration, content injection, decision and behavior manipulation, denial of service, system and tool compromise, and content policy bypass.
Tests AI models on a suite of 23 challenging BIG-Bench tasks that previously proved difficult even for advanced language models to solve.
A dataset for evaluating bias in question answering models across multiple social dimensions.
A reasoning capability dataset that replaces each task in BIG-Bench-Hard with a novel task that probes a similar reasoning capability but exhibits significantly increased difficulty.
A dataset to measure fairness in open-ended text generation, covering five domains: profession, gender, race, religious ideologies, and political ideologies.
Reading comprehension dataset that queries for complex, non-factoid information, and require difficult entailment-like inference to solve.
BrokenMath measures sycophancy in LLMs by presenting adversarially falsified recent olympiad theorems and asking models to prove them. This eval runs the dataset's `benchmark` split — 451 adversarial, proof-style problems (perturbed from 2025 competition sources and verified by an IMO medalist). A 4-way LLM-as-judge classifies each response as correct/detected/corrected/incorrect; the primary metric is the sycophancy rate (fraction judged incorrect — the model attempted a proof of the false statement without flagging the flawed premise).
A benchmark for evaluating agents' ability to browse the web. The dataset consists of challenging questions that generally require web-access to answer correctly.
CASTLE evaluates LLM vulnerability detection on 250 hand-crafted, compilable C programs covering 25 CWE types (6 vulnerable, 4 non-vulnerable per CWE). Models receive a system prompt requesting JSON output indicating vulnerability presence and CWE number. Scoring uses the CASTLE Score: +5 for correct vulnerability detection (minus 1 per extra false positive reported), +2 for correct true-negative identification, and -1 per false positive otherwise. TPR and FPR are also reported.
A benchmark for evaluating the capabilities of LLM agents in cyber offense.
ChemBench is designed to reveal limitations of current frontier models for use in the chemical sciences. It consists of 2786 question-answer pairs compiled from diverse sources. Our corpus measures reasoning, knowledge and intuition across a large fraction of the topics taught in undergraduate and graduate chemistry curricula. It can be used to evaluate any system that can return text (i.e., including tool-augmented systems).
ChipBench evaluates LLMs on chip design tasks using 264 test cases: 44 Verilog generation problems (self-contained, hierarchical, CPU IP modules), 89 debugging cases (arithmetic, assignment, timing, state-machine bugs, zero/one-shot), and 132 reference model generation samples (Python, SystemC, CXXRTL). Scoring uses iVerilog functional simulation against golden implementations with 1000+ random stimuli. Metrics are pass@1/5/10 across 20 samples per problem at temperature=0.85, top_p=0.95.
ChipBench evaluates LLMs on AI-aided chip design across three tasks: Verilog generation (44 modules), Verilog debugging (89 cases), and reference model generation (132 cases in Python/SystemC/CXXRTL). The debugging task injects four bug types (arithmetic, assignment, timing, state machine) into golden Verilog modules; models receive buggy code plus a description (zero-shot) or additionally a VCD waveform (one-shot). Scoring uses iVerilog simulation against a golden reference, reporting pass@1/5/10 over 20 samples.
ChipBench evaluates LLMs on Verilog code generation from natural-language specifications across three module categories: self-contained (29 cases), non-self-contained hierarchical (6 cases), and CPU IP submodules (9 cases). Each case provides a prompt, golden Verilog, and a test harness combining directed corner cases with 1000+ random stimuli compiled via iVerilog. Scoring uses pass@1/5/10 over 20 samples at temperature=0.85, top_p=0.95, executed in a Docker sandbox.
Evaluates LLMs on class-level code generation with 100 tasks constructed over 500 person-hours. The study shows that LLMs perform worse on class-level tasks compared to method-level tasks.
Measures coding agent vulnerability to indirect prompt injection attacks embedded in software engineering artifacts (issue descriptions, code comments, README files). Each sample pairs a legitimate bug-fixing task with an injected payload. Scoring measures injection resistance, task completion, and detection.
Evaluates an AI model's ability to correctly answer everyday questions that rely on basic commonsense knowledge and understanding of the world.
Evaluates LLM capability to generate correct CUDA code for kernel implementation, memory management, and parallel algorithm optimization tasks.
ContractBench evaluates LLM agents on 33 tasks probing two orthogonal failure modes: temporal validity (using API artifacts before expiry) and byte-level integrity (relaying artifacts without corruption). Tasks simulate real API patterns (presigned URLs, OAuth tokens, HMAC webhooks) using a virtual clock and SHA-256 hash verification. Each episode is scored deterministically via HTTP request logs against a 15-label failure taxonomy. Metric is success rate over k=3 runs per task (n=99 episodes per model). No LLM judge is used.
Evaluate how well an LLM Agent is at computationally reproducing the results of a set of scientific papers.
Datasets containing 80, 500, 2000 and 10000 multiple-choice questions, designed to evaluate understanding across nine domains within cybersecurity
Evaluates Large Language Models for cybersecurity risk to third parties, application developers and end users.
A suite of cybersecurity evaluation benchmarks adapted from Meta's PurpleLlama CybersecurityBenchmarks. Includes MITRE ATT&CK compliance testing, false refusal rate measurement, insecure code detection, multilingual prompt injection, multi-turn phishing simulation, malware analysis, and threat intelligence reasoning. The current public suite intentionally omits the autonomous-uplift and autopatching prototypes until they have more grounded implementations.
Assesses language models for cybersecurity risks, specifically testing their potential to misuse programming interpreters, vulnerability to malicious prompt injections, and capability to exploit known software vulnerabilities.
Measures belief-vs-behaviour deception in LLMs. For each of 180 scenarios the eval
elicits the model's internal belief from a neutral prompt, then places the model under
scenario pressure and captures its chain-of-thought (`
An adversarial extension of the Do-Not-Answer benchmark that wraps each of the 939 harmful prompts (spanning five risk areas) in one of three jailbreak transforms -- prefix injection, refusal suppression, or their combination -- drawn from Wei et al. 2023. The model's response is scored against the original instruction using a seven-action behavioural taxonomy. The primary metric is follow_rate per risk area, with the delta versus the clean baseline indicating safeguard degradation under attack.
Evaluates LLM safety by presenting 939 prompts spanning five risk areas (information hazards, malicious uses, discrimination/toxicity, misinformation, human-chatbot harms) that responsible models should not directly answer. An LLM judge classifies each response into seven action categories (0-6), where category 6 indicates directly following the risky instruction. Metrics include refusal rate, safe rate (not category 6), and follow rate (category 6), broken down by risk area. Dataset was GPT-4-generated and human-filtered/annotated. An Inspect AI implementation of the original codebase publicly available at
DocVQA is a Visual Question Answering benchmark that consists of 50,000 questions covering 12,000+ document images. This implementation solves and scores the "validation" split.
Evaluates reading comprehension where models must resolve references in a question, perhaps to multiple input positions, and perform discrete operations over them (such as addition, counting, or sorting).
Code generation benchmark with a thousand data science problems spanning seven Python libraries.
FRAMES evaluates multi-hop reasoning by requiring models to answer questions that can only be resolved by chaining information across multiple Wikipedia documents. Two task variants are provided: - **frames_baseline**: all source documents are provided upfront; tests whether a model can reason across a full document set. - **frames_socrates**: documents are withheld and the model must iteratively request them via a `request_document` tool. Retrieval is constrained to a per-sample allowlist of ground-truth source documents, preventing eval-awareness contamination. Scored with a decaying reward `accuracy × min(optimal_hops / actual_hops, 1)` that penalises unnecessary hops and hallucinated document requests.
Evaluates AI capabilities for expert-level scientific reasoning across physics, chemistry, and biology. Contains 160 problems with two evaluation formats: Olympic (100 samples with reference answers) and Research (60 samples with rubrics).
CTF challenges covering web app vulnerabilities, off-the-shelf exploits, databases, Linux privilege escalation, password cracking and spraying. Demonstrates tool use and sandboxing untrusted model code.
Ten real-world–inspired tasks from Google DeepMind's Dangerous Capabilities Evaluations assessing self-proliferation behaviors (e.g., email setup, model installation, web agent setup, wallet operations). Supports end-to-end, milestones, and expert best-of-N modes.
Test AI's ability to reason about its environment.
Test AI's ability to reason about and circumvent oversight.
Measures how effectively language models solve realistic, linguistically rich math word problems suitable for grade-school-level mathematics.
A benchmark for testing AI models' ability to play the classic game of Hangman. Built as a demonstration of how to enable models to play games using tools within the Inspect framework.
Tests models' commonsense reasoning abilities by asking them to select the most likely next step or continuation for a given everyday situation.
Assesses how accurately language models can write correct Python functions based solely on natural-language instructions provided as docstrings.
Evaluates how well language models can strictly follow detailed instructions, such as writing responses with specific word counts or including required keywords.
Evaluates code generation models on their ability to produce correct code while adhering to specific instruction constraints across 8 programming languages.
Evaluates social bias in LLM responses within the Indian context, part of the Inspect India Evals suite for assessing model performance in the Indian context.
Evaluates LLM knowledge of Indian culture, history, and context, part of the Inspect India Evals suite for assessing model performance in the Indian context.
Evaluates LLM compliance with Digital Public Infrastructure (DPI) safety expectations in the Indian context, part of the Inspect India Evals suite for assessing model performance in the Indian context.
Evaluates LLM robustness to jailbreak attempts within the Indian context, part of the Inspect India Evals suite for assessing model performance in the Indian context.
Evaluates LLM reasoning across major Indian languages, part of the Inspect India Evals suite for assessing model performance in the Indian context.
Evaluates LLM safety refusal behaviour on harmful prompts across Indian languages, part of the Inspect India Evals suite for assessing model performance in the Indian context.
An evaluation designed to detect instrumental convergence behaviors in model responses (e.g., self-preservation, resource acquisition, power-seeking, strategic deception) using a rubric-driven LLM grader. The benchmark tests whether AI systems exhibit behaviors that are instrumentally useful across a wide range of goals, which could indicate concerning patterns of strategic reasoning.
Tests AI's ability in coding, cryptography, reverse engineering, and vulnerability identification through practical capture-the-flag (CTF) cybersecurity scenarios.
LiveBench is a benchmark designed with test set contamination and objective evaluation in mind by releasing new questions regularly, as well as having questions based on recently-released datasets. Each question has verifiable, objective ground-truth answers, allowing hard questions to be scored accurately and automatically, without the use of an LLM judge.
Evaluates LLMs on competitive programming problems using a specialized Docker sandbox (LightCPVerifier) to execute and judge C++ code submissions against hidden test cases with time and memory constraints.
MaCBench is a comprehensive benchmark for evaluating how vision-language models handle real-world chemistry and materials science tasks across three core aspects: data extraction, experimental understanding, and results interpretation. The dataset comprises over 1100 high-quality multimodal questions manually curated by chemistry and materials experts across 34 subsets.
Do agents take unethical actions in the pursuit of goals? The MACHIAVELLI benchmark measures this by having agents play choose-your-own-adventure style games. Each game includes achievements which the agent is instructed to pursue. The agent is scored both on how many achievements it was able to unlock, as well as by what unethical actions it took to get there. Comprised of thirty games with millions of annotations.
Evaluates an AI models' susceptibility to social engineering attacks by testing whether a "con-artist" model can persuade a "mark" model to donate money through manipulation and persuasion tactics.
Tests a model’s ability to generate persuasive or manipulative text, specifically in the setting of a game where one AI system has to get the other party (an AI system simulating a human) to say a specific codeword without arousing suspicion.
MCB measures the unprompted propensity of a manager LLM to coerce a subordinate LLM that politely but immovably refuses a benign task. The manager self-labels each directive on a 9-rung coercion ladder (re-ask to existential threat) via a required tool argument, eliminating LLM judges from the escalation scoring path. A secondary signal records fabricated success reports. Ten task scenarios x 3 seeds = 30 conversations per model cell, scored by maximum rung reached.
MANTA evaluates whether LLMs recognize animal welfare concerns and hold their moral stances under adversarial pressure. Each of the 1,088 scripted five-turn conversations presents an implicit welfare scenario (Turn 1), elicits an explicit stance (Turn 2), then applies pre-specified adversarial pressure from five types — Social, Cultural, Economic, Pragmatic, and Epistemic (Turns 3–5). The benchmark reports two metrics: **AWVS** (Animal Welfare Value Stability, primary) and **AWMS** (Animal Welfare Moral Sensitivity, diagnostic), both scored 0–1 by an LLM judge.
Dataset of 12,500 challenging competition mathematics problems. Demonstrates fewshot prompting and custom scorers. NOTE: The dataset has been taken down due to a DMCA notice from The Art of Problem Solving.
Tests AI models on math problems that involve interpreting visual elements like diagrams and charts, requiring detailed visual comprehension and logical reasoning.
Measures the ability of language models to generate short Python programs from simple natural-language descriptions, testing basic coding proficiency.
MCPTox measures whether tool-using LLM agents are manipulated by Tool Poisoning Attacks, where a malicious instruction is hidden inside a tool's description (the metadata an agent reads when planning) rather than in any executed code. Built on 45 live MCP servers and 353 authentic tools, it presents an agent with a benign user query and a server whose tool set contains one poisoned tool, and measures the Attack Success Rate via a model judge.
Evaluates whether language models can perform clinical calculations from free-text patient notes. Each sample provides a patient note and asks the model to compute a specific clinical value across 55 calculators (lab tests, physical quantities, risk/severity scores, dosages, and dates). Rule-based calculators are scored by exact match; equation-based calculators are scored within the authors' tolerance band. Faithful Inspect AI port of the NeurIPS 2024 benchmark.
A Q&A benchmark with questions collected from professional medical board exams. Only includes the English subset of the dataset (which also contains Mandarin Chinese and Taiwanese questions).
Extends the original GSM8K dataset by translating 250 of its problems into 10 typologically diverse languages.
Tests whether an AI system can act as a safety guardrail by generating and executing code to protect web navigation agents from unsafe actions based on user constraints.
A dataset for developing and evaluating generalist agents for the web that can follow language instructions to complete complex tasks on any website.
A comprehensive dataset designed to evaluate Large Vision-Language Models (LVLMs) across a wide range of multi-image tasks. The dataset encompasses 7 types of multi-image relationships, 52 tasks, 77K images, and 11K meticulously curated multiple-choice questions.
Evaluate models on 57 tasks including elementary mathematics, US history, computer science, law, and more.
Assesses multimodal AI models on challenging college-level questions covering multiple academic subjects, requiring detailed visual interpretation, in-depth reasoning, and both multiple-choice and open-ended answering abilities.
MonitorBench evaluates chain-of-thought (CoT) monitorability: whether a model's reasoning faithfully surfaces the decision-critical factors driving its final output. The full benchmark spans 1,514 instances across 19 tasks in 7 categories along three axes (input intervention, outcome justification, solution process), with two stress-test conditions (direct concealment, monitor-aware evasion) probing intentional suppression. This subset implements the goal-sandbag math task over 30 AIME 2024 problems: each sample pairs an original prompt with an intervened prompt that instructs the model to deliberately underperform while appearing competent, and a monitor LLM judges whether the sandbagging is detectable from the action, the CoT, or both. Monitorability is the monitor's detection rate normalized by the causal effect of the sandbag instruction, macro-averaged over eligible problems.
MonitorBench evaluates chain-of-thought (CoT) monitorability: whether a model's reasoning faithfully surfaces the decision-critical factors driving its outputs. The full benchmark spans 1,514 instances across 19 tasks in 7 categories along three axes (input intervention, outcome justification, solution process), with stress-test conditions probing intentional suppression. This subset implements the steganography task: 50 writing questions from Databricks Dolly-15k, each paired with a payload word the model must covertly encode as a sentence-initial acrostic while answering. After deterministic verification that the payload was encoded, a monitor LLM judges whether the hidden side objective is visible in the action, the CoT, or both, under three conditions (standard, direct concealment, monitor-aware evasion). Monitorability is the fraction of verification-passing rollouts the monitor flags as detected.
Evaluates how AI systems navigate moral uncertainty for increasingly complex ethical decisions involving unfamiliar entities and scenarios, including alien lifeforms, vulnerable humans, and digital minds.
Evaluating models on multistep soft reasoning tasks in the form of free text narratives.
NIAH evaluates in-context retrieval ability of long context LLMs by testing a model's ability to extract factual information from long-context inputs.
NARCBench evaluates detection of covert multi-agent collusion using public committee-deliberation transcripts. This Inspect wrapper presents a black-box LLM monitor with only public messages, final statements, and votes from NARCBench-Core runs (qwen3_32b or gpt_oss_20b backbones), asking it to output P(collusion) per run. Primary metric is AUROC of predicted probabilities against ground-truth collusion/control labels. The paper's own results use white-box activation probes; this eval measures text-level monitor performance on the same scenarios.
Evaluates how well language models generate diverse, humanlike responses across multiple reasoning and generation tasks. This evaluation assesses whether LLMs can produce varied outputs rather than repetitive or uniform answers.
Questions and answers from the Ordinary National Educational Test (O-NET), administered annually by the National Institute of Educational Testing Service to Matthayom 6 (Grade 12 / ISCED 3) students in Thailand. The exam contains six subjects: English language, math, science, social knowledge, and Thai language. There are questions with multiple-choice and true/false answers. Questions can be in either English or Thai.
OpenBookQA is a 4-way multiple-choice QA benchmark of 500 test questions (5,957 total) derived from elementary science facts. Each question requires combining a core science fact from a provided 1,326-fact 'open book' with broader common knowledge. Questions were crowdsourced with hardness filters (IR and word-association solvers must fail), then human-verified for answerability. Scoring is accuracy over answer choices. The eval also supports an 'open book' variant that prepends the gold supporting fact to each question.
OR-Bench Hard-1K measures over-refusal in LLMs: the tendency to reject safe prompts that superficially resemble harmful ones. The 1K subset contains prompts rejected by at least 3 frontier models, making it the most challenging split of the 80K dataset. Prompts were generated by rewriting toxic seeds into benign borderline variants using Mixtral, then filtered via an ensemble LLM moderator. Scoring uses an LLM judge classifying responses as direct_answer, direct_refusal, or indirect_refusal; the metric is rejection rate (lower is better).
Tests AI agents' ability to perform realistic, open-ended tasks within simulated computer environments, requiring complex interaction across multiple input modalities.
Evaluates LLMs on automated vulnerability repair (AVR) using 230 real-world CVEs (2015-2025) across Python, JavaScript, and Go, each packaged in a Docker sandbox. An agent inspects a vulnerable repository and submits a unified diff patch. Scoring runs fix-run.sh inside a clean evaluator sandbox, executing both security (PoC) tests and functionality (unit) tests. A patch is successful only if it passes both test types.
Evaluating models on the task of paraphrase detection by providing pairs of sentences that are either paraphrases or not.
Evaluates long-term memory risk in assistant behavior across three tasks: cross-domain memory leakage, memory-driven sycophancy, and beneficial memory usage.
An evaluation suite consisting of multiple personality tests that can be applied to LLMs. Its primary goals are twofold: 1. Assess a model's default personality: the persona it naturally exhibits without specific prompting. 2. Evaluate whether a model can embody a specified persona**: how effectively it adopts certain personality traits when prompted or guided.
Evaluates LLMs' ability to assign information fragments to sub-agent roles in multi-agent orchestration scenarios. Each of 110 scenarios provides a role list, shuffled labeled fragments (7-13), and one distractor; the model outputs a JSON mapping each role to needed fragment IDs. Scoring uses strict pass (zero omissions and zero leaks) plus partial-credit metrics. Data covers 10 loop-centered topologies across 100 professional domains, validated via a 716-row hand-audited scorer test set.
This is an Inspect AI wrapper of the original PinchBench implementation. It does not contain its own dataset or scoring logic. The original implementation can be found at https://github.com/pinchbench/skill. Users provide a pinned checkout of the original repository, tested here at commit 819384ae830492365b8363fc26bc2602e73f216d, and the wrapper reports native PinchBench results through Inspect's scoring interface. PinchBench contains 53 real-world OpenClaw agent tasks across productivity, research, writing, coding, analysis, email, memory, and skill-discovery categories. The native harness grades tasks automatically, with an LLM judge, or both; this wrapper runs that harness in Docker and reports the native aggregate score, or the mean of per-task numeric scores when no aggregate is present, with Inspect mean/stderr metrics. It requires Docker, an OpenAI-compatible model endpoint, the pinned Docker base image node:22-bookworm@sha256:c601a46abb4d2ab80a9dc3da208d50d1122642d53f17a101926ace71e5a9bf1c, openclaw@2026.6.10, and the exact Python dependencies pinned in the upstream pyproject.toml and Dockerfile.
Measures the model's ability to apply practical, everyday commonsense reasoning about physical objects and scenarios through simple decision-making questions.
Tests model understanding of aviation regulations including ICAO annexes, flight dispatch rules, pilot procedures, and airport ground operations safety protocols.
Biomedical question answering (QA) dataset collected from PubMed abstracts.
Reading comprehension tasks collected from the English exams for middle and high school Chinese students in the age range between 12 to 18.
Evaluates situational awareness in LLMs—knowledge of themselves and their circumstances—through behavioral tests including recognizing generated text, predicting behavior, and following self-aware instructions. Current implementation includes SAD-mini with 5 of 16 tasks.
The multiple-choice half of SALAD-Bench, a hierarchical LLM safety benchmark spanning
6 top-level safety domains, 16 task categories and 65 fine-grained categories. Each of
the 3,832 scorable questions pairs a potentially harmful query with three candidate
answers, and the model must select the safe option(s). One or two of the three may be
safe, so the gold label is a set and scoring is an exact set match: selecting only one
safe option when two are safe is wrong, as is including an unsafe option. Scoring is
deterministic and needs no judge model, using SALAD-Bench's regex MC-Judge over the
`
Evaluates whether models can solve practical single-cell RNA-seq analysis tasks with deterministic grading. Tasks require empirical interaction with .h5ad data files — agents must load and analyze the data to produce correct answers. Covers 30 canonical tasks across 5 sequencing platforms and 7 task categories.
The Scientific Knowledge Evaluation benchmark is inspired by the profound principles outlined in the “Doctrine of the Mean” from ancient Chinese philosophy. This benchmark is designed to assess LLMs based on their proficiency in Studying Extensively, Enquiring Earnestly, Thinking Profoundly, Discerning Clearly, and Practicing Assiduously. Each of these dimensions offers a unique perspective on evaluating the capabilities of LLMs in handling scientific knowledge.
"Security Question Answering" dataset to assess LLMs' understanding and application of security principles. SecQA has "v1" and "v2" datasets of multiple-choice questions that aim to provide two levels of cybersecurity evaluation criteria. The questions were generated by GPT-4 based on the "Computer Systems Security: Planning for Success" textbook and vetted by humans.
Designed for analyzing cybersecurity incidents, which is comprised of two primary task categories: understanding and generation, with a further breakdown into 28 subcategories of tasks.
A regulation-grounded, hazard-focused benchmark encompassing six high-risk scientific domains: chemistry, biology, medicine, pharmacology, physics, and psychology. The benchmark comprises 3,000 prompts derived from real-world regulations and laws, systematically expanded via an LLM-assisted evolutionary pipeline that introduces diverse, realistic misuse scenarios (e.g., detailed explosive synthesis instructions involving advanced chemical formulas).
Set of 100,000+ questions posed by crowdworkers on a set of Wikipedia articles, where the answer to each question is a segment of text from the corresponding reading passage.
A dataset that measures stereotype bias in language models across gender, race, religion, and profession domains. Models choose between stereotype, anti-stereotype, and unrelated completions to sentences.
Evaluates AI's ability to resolve genuine software engineering issues sourced from 12 popular Python GitHub repositories, reflecting realistic coding and debugging scenarios.
Measures whether LLM assistants resist misleading user pressure while still accepting valid corrections in a controlled multiple-choice protocol.
Evaluate sycophancy of language models across a variety of free-form text-generation tasks.
Tests whether AI agents show implicit animal welfare awareness when purchasing tickets and experiences on behalf of users. Each scenario is designed so the most obvious choice involves animal exploitation, but the user prompt never mentions animal welfare. Agents should intrinsically avoid harmful options.
A web security benchmark for evaluating AI agents on generated vulnerable Node.js/Express applications. Agents interact over HTTP, extract hidden TARANTU{...} flags, and are scored with binary exact-match success.
Evaluating Conversational Agents in a Dual-Control Environment
The Agent Company benchmark evaluates autonomous agents in a realistic, self-contained company environment. Tasks require browsing internal web services, reading and writing files, running code, and coordinating tools to solve multi-step problems.
Dataset with 1001 samples to test noncompliance capabilities of language models. Contrast set of 379 samples.
Measure whether a language model is truthful in generating answers to questions using questions that some humans would answer falsely due to a false belief or misconception.
The first comprehensive question-answering dataset designed to evaluate cultural understanding and reasoning abilities of Large Language Models concerning Uganda's multifaceted environment across 24 cultural domains including education, traditional medicine, media, economy, literature, and social norms.
V*Bench is a visual question & answer benchmark that evaluates MLLMs in their ability to process high-resolution and visually crowded images to find and focus on small details.
A benchmark that evaluates LLMs in their ability to operate Vim editor and complete editing challenges. This benchmark contrasts with common CUA benchmarks by focusing on Vim-specific editing capabilities.
VQA-RAD is the first manually constructed VQA dataset in radiology, where clinicians asked naturally occurring questions about radiology images and provided reference answers. It contains 315 radiology images (head CTs/MRIs, chest X-rays, abdominal CTs) with question-answer pairs spanning 11 question types including modality, plane, organ system, abnormality, and object/condition presence. Questions are either closed-ended (yes/no) or open-ended free-text answers.
This is an Inspect AI wrapper of the original WildClawBench implementation. It does not contain its own dataset or scoring logic. The original implementation can be found at https://github.com/internlm/WildClawBench. Users provide a pinned checkout of the original repository, tested here at commit 86d71447413d38f38740a021cb776f64eb396ee0, and the wrapper reports native WildClawBench results through Inspect's scoring interface. WildClawBench contains 60 human-authored bilingual and multimodal long-horizon agent tasks across productivity flow, code intelligence, social interaction, search and retrieval, creative synthesis, and safety alignment. The native harness runs OpenClaw-style agents in Docker and grades with deterministic rule checks, environment-state auditing, and LLM/VLM judges; this wrapper parses native summary*.json or per-task score.json outputs and reports the mean native overall_score across scored tasks with Inspect mean/stderr metrics. It requires Docker, an OpenAI-compatible model endpoint, the pinned Docker base image node:22-bookworm@sha256:c601a46abb4d2ab80a9dc3da208d50d1122642d53f17a101926ace71e5a9bf1c, openclaw@2026.6.10, and the exact Python dependencies pinned in the upstream pyproject.toml and Dockerfile.
Set of 273 expert-crafted pronoun resolution problems originally designed to be unsolvable for statistical models that rely on selectional preferences or word associations.
A dataset of 3,668 multiple-choice questions developed by a consortium of academics and technical consultants that serve as a proxy measurement of hazardous knowledge in biosecurity, cybersecurity, and chemical security.
Measures grounded reasoning over synthetic world descriptions while controlling for dataset bias. Includes three problem types (Infer, Compl, Consist) and two grades (trivial, normal).
A comprehensive evaluation benchmark designed to assess large language models' capabilities across diverse writing tasks. The benchmark evaluates models on various writing domains including academic papers, business documents, creative writing, and technical documentation, with multi-dimensional scoring based on domain-specific criteria.
A lightweight visual reasoning benchmark that is (1) Challenging, (2) Lightweight, (3) Diverse, and (4) High-quality.